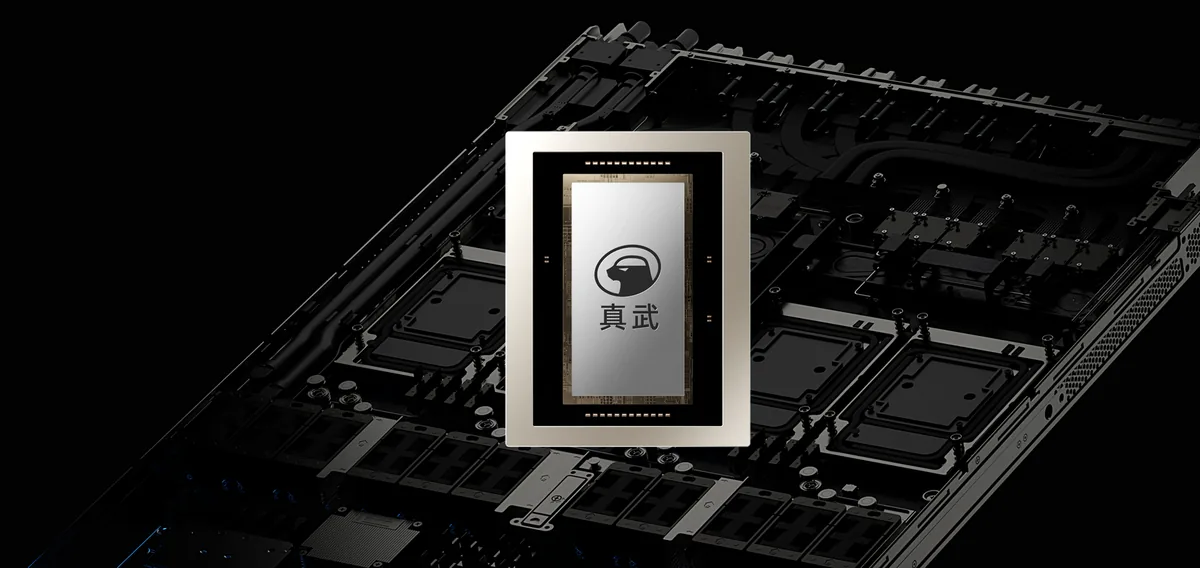
Zhenwu V900 Training & Inference AI Chip
Product in T-Head's official AI-chip section. End-to-end self-developed hardware with deeply iterated parallel-compute architecture and interconnect. The self-developed T-Head SAIL® stack provides a unified API minimizing migration code changes; supports multi-process sharing and multi-tenant isolation. Official specs: 216 GB memory; 1200 GB/s inter-chip interconnect; enhanced FP8/FP4 instruction precision. Built on the self-developed ICN interconnect bus; two layers of ICN Switch can form a 1024-chip cluster-scale full-bandwidth Scale-Up domain with unified memory semantics and consistent...
Key Highlights
- High performance: 216 GB memory, 1200 GB/s interconnect, enhanced FP8/FP4, 1024-chip full-bandwidth interconnect
- symmetric Scale-Up bandwidth and unified memory addressing via ICN Switch
- full precision range FP32 to FP4
- co-designed SAIL® software stack
- flexible deployment
Technical Specifications
| Memory Capacity | 216 GB |
|---|---|
| Inter-chip Bandwidth | 1200 GB/s(自研 ICN 总线 / proprietary ICN bus) |
| Low Precision | FP8 / FP4(含 MXFP8/MXFP4 缩放格式 / MXFP8/MXFP4 scaling) |
| Interconnect Scale | 两层 ICN Switch,1024 芯片 Scale-Up 全带宽域 / 1024-chip Scale-Up fabric |
| Software Stack | T-Head SAIL®(统一 API,软硬协同 / unified API, co-designed) |
| Process, TDP, Form Factor | 官网未公布 / not disclosed |
Typical Use Cases
1024 卡为 Scale-Up 组网能力描述(两层 ICN Switch 组网),非单芯片硬件规格;官网公开为芯片级规格,未公布 TDP、制程、板卡尺寸与公开 PDF datasheet(完整 datasheet 需商务合作/工单);产品通过阿里云生态与合作渠道交付;图片为官网产品页主视觉渲染图(芯片模组置于液冷加速板上);category 取 accelerator_card,交付形态以官方云实例/商务方案为准。本地图片为官网产品页主视觉的产品区域裁剪版(裁剪掉左侧空白),原始图见 image_source_urls。
Related Products
Atlas 300I A2 Inference Card
High-performance AI inference card integrated into servers View details →
Atlas 300I Pro Inference Card
Inference accelerator card integrated into servers View details →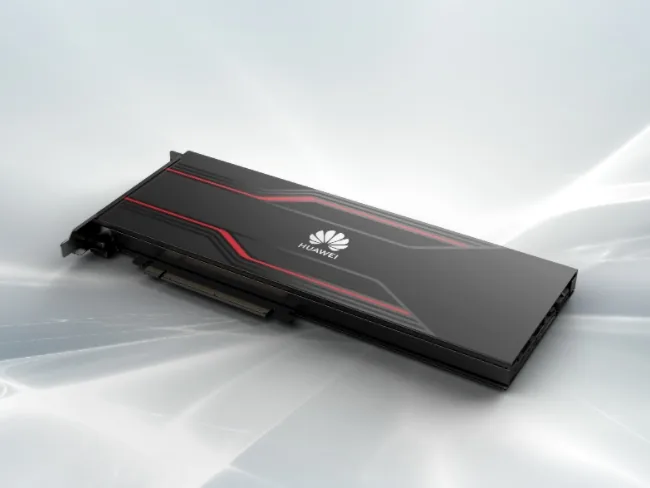
Atlas 300I Duo Inference Card
Dual-chip high-density inference accelerator card View details →