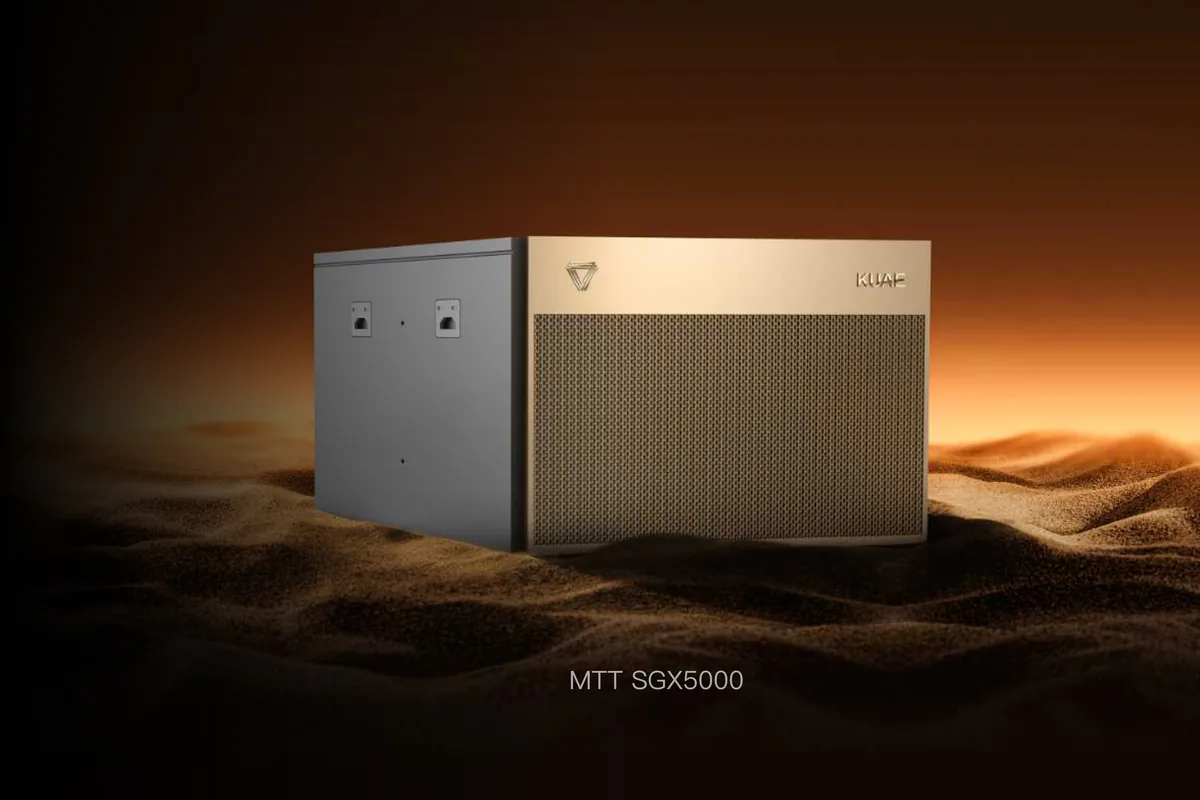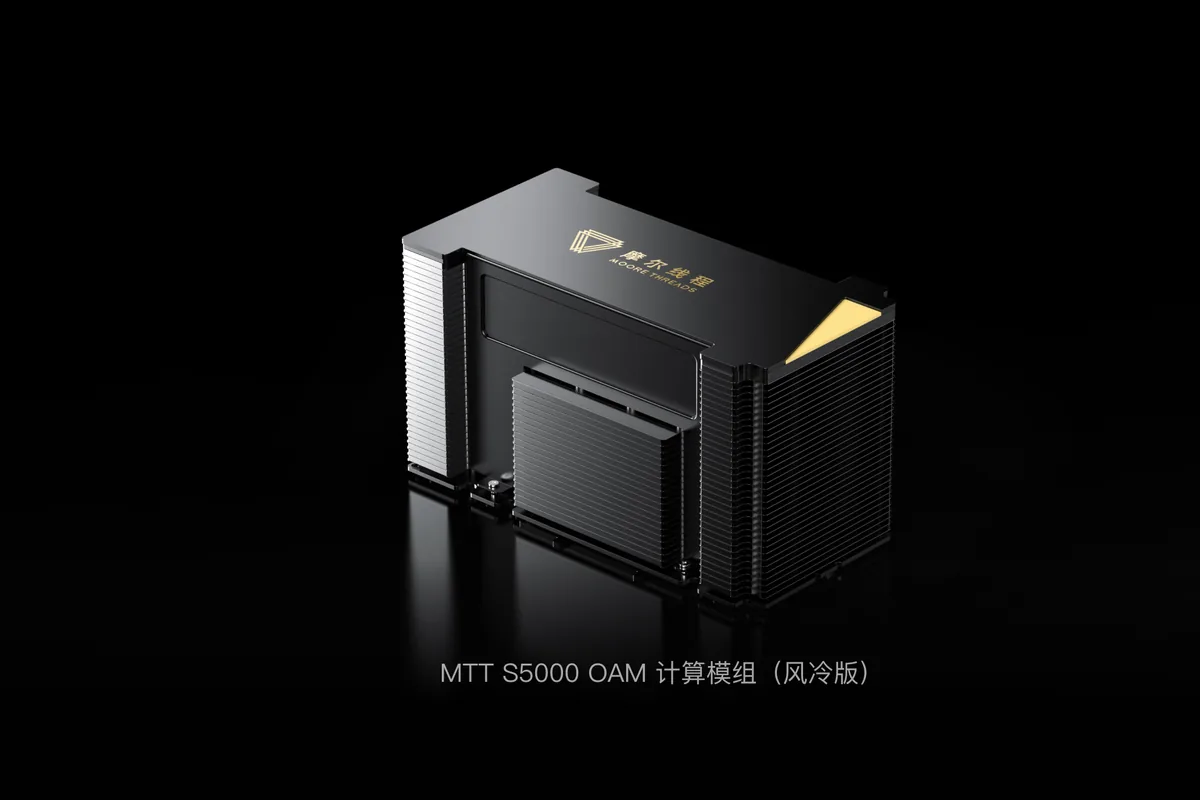
MTT S5000
MTT S5000 is a Universal GPU engineered for the generative AI era, purpose-built for large model training, inference, and high-performance computing. With Moore Threads' next-generation PH100 chip and the advanced PingHu architecture, it delivers full-precision compute from FP8 to FP64. Powered by the fourth-generation MUSA full-stack platform with native support for PyTorch, Megatron-LM, vLLM and SGLang, it enables near-zero-effort code migration. PH100 was among the first chips to receive security and reliability certification from the China Information Technology Security Evaluation Center...
Key Highlights
- Hardware-native FP8 with over 30% training improvement on DeepSeek/Qwen-class architectures
- designed for 10K-GPU clusters with up to 95% scaling linearity and chip-to-system RAS raising training success rate by over 30%
- per-card Prefill over 4000 Tokens/s and Decode over 1000 Tokens/s (PD-disaggregated, six 8-GPU S5000 servers, native FP8)
- 16 GPUs
- native FP64
- CUDA-compatible MUSA migration
- OAM modules in liquid-cooled and air-cooled versions.
Technical Specifications
| 芯片/Chip | PH100 |
|---|---|
| 架构/Architecture | PingHu(平湖), 4th-gen MUSA |
| 精度/Precision | FP8/FP16/BF16/FP32/TF32/FP64 |
| 形态/Form Factor | OAM compute module (air-cooled / liquid-cooled) |
| 互联/Interconnect | MTLink |
| On-card memory & per-card TOPS-TFLOPS | 官网未公开量化值 (Not published on official page) |
Typical Use Cases
英文取自官网英文页;官网未公开 S5000 自身显存容量/带宽与单卡算力量化规格,页脚①②③为竞品对比基准、未采信为产品参数;官网 cover.jpg/banner.jpg 为纯背景空图(无产品主体)未采用,图片采用官网 row-3-1.jpg(MTT S5000 OAM 计算模组风冷版渲染图,含官方图注)。
Related Products
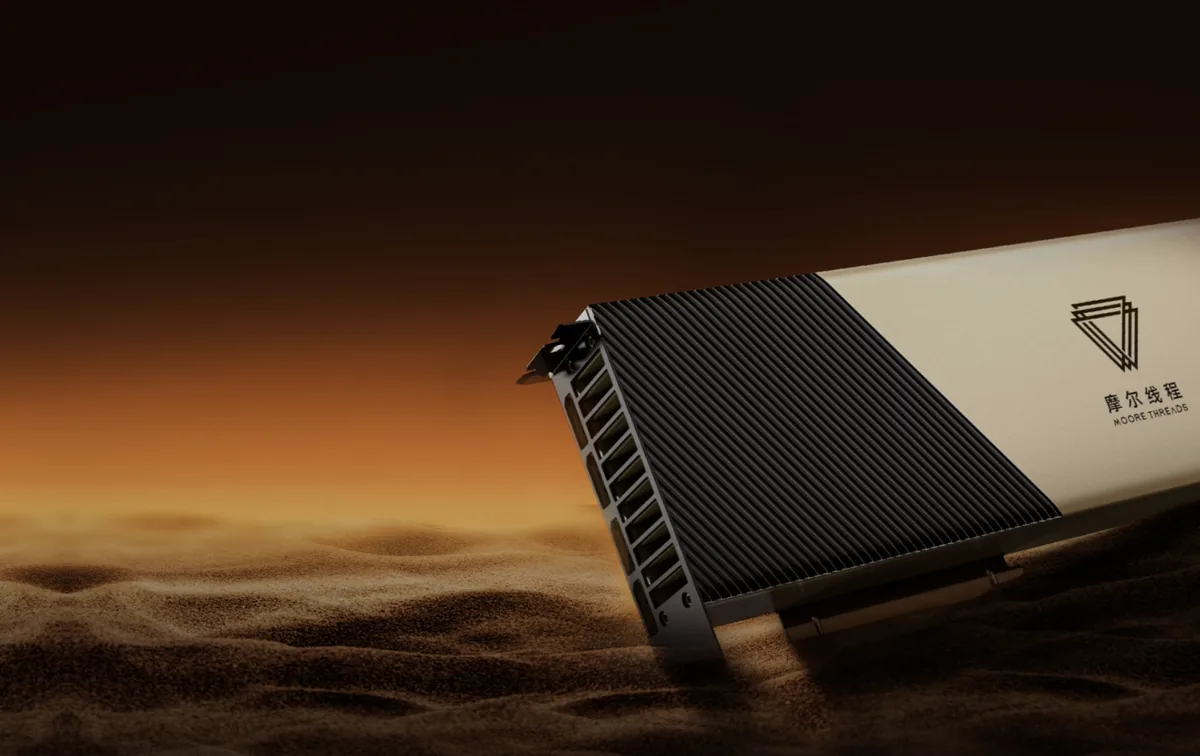
MTT S4000
Large-model AI inference and training GPU with Tensor Cores View details →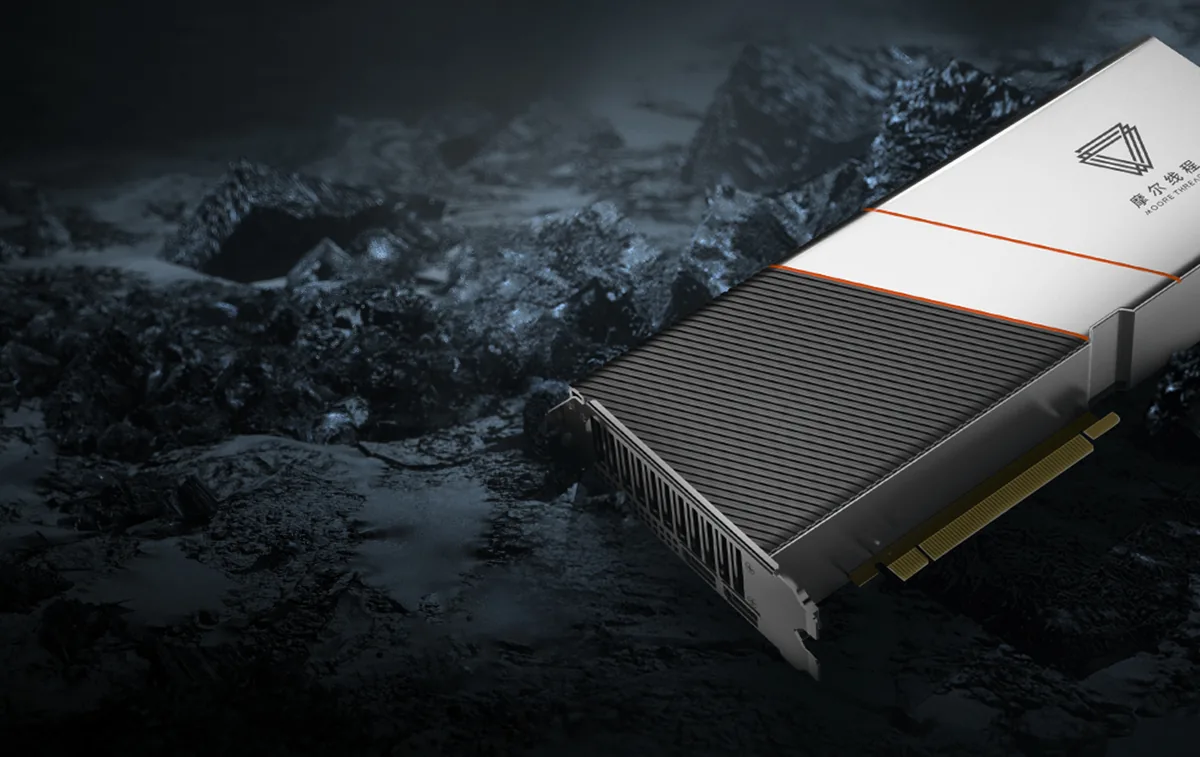
MTT S3000
Full-featured server-class GPU View details →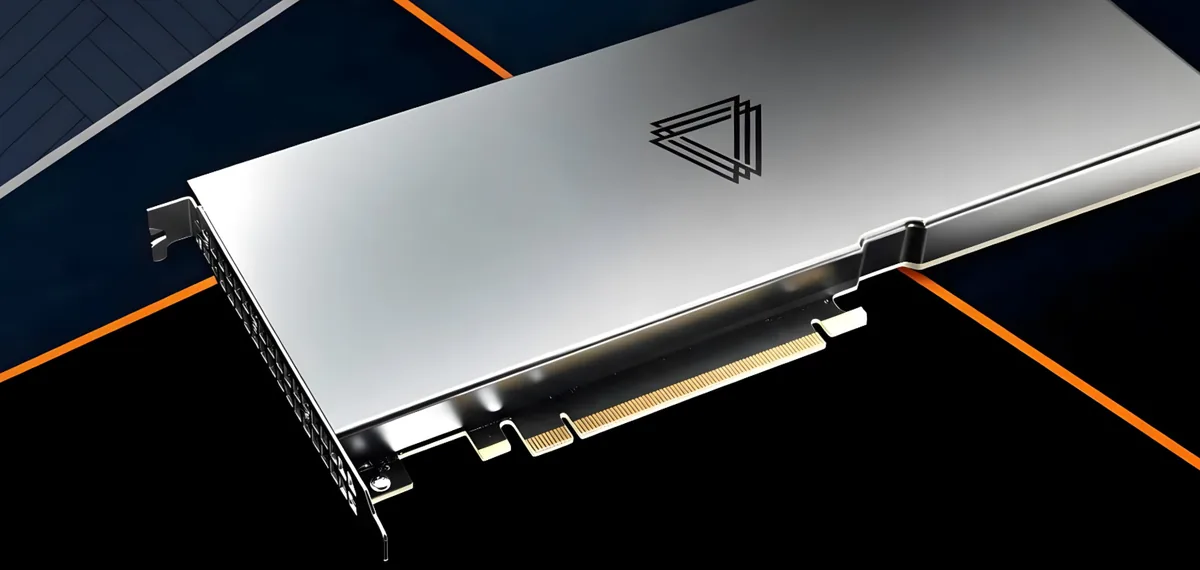
MTT S2000
Low-power full-featured server GPU for cloud-native workloads (translation draft) View details →